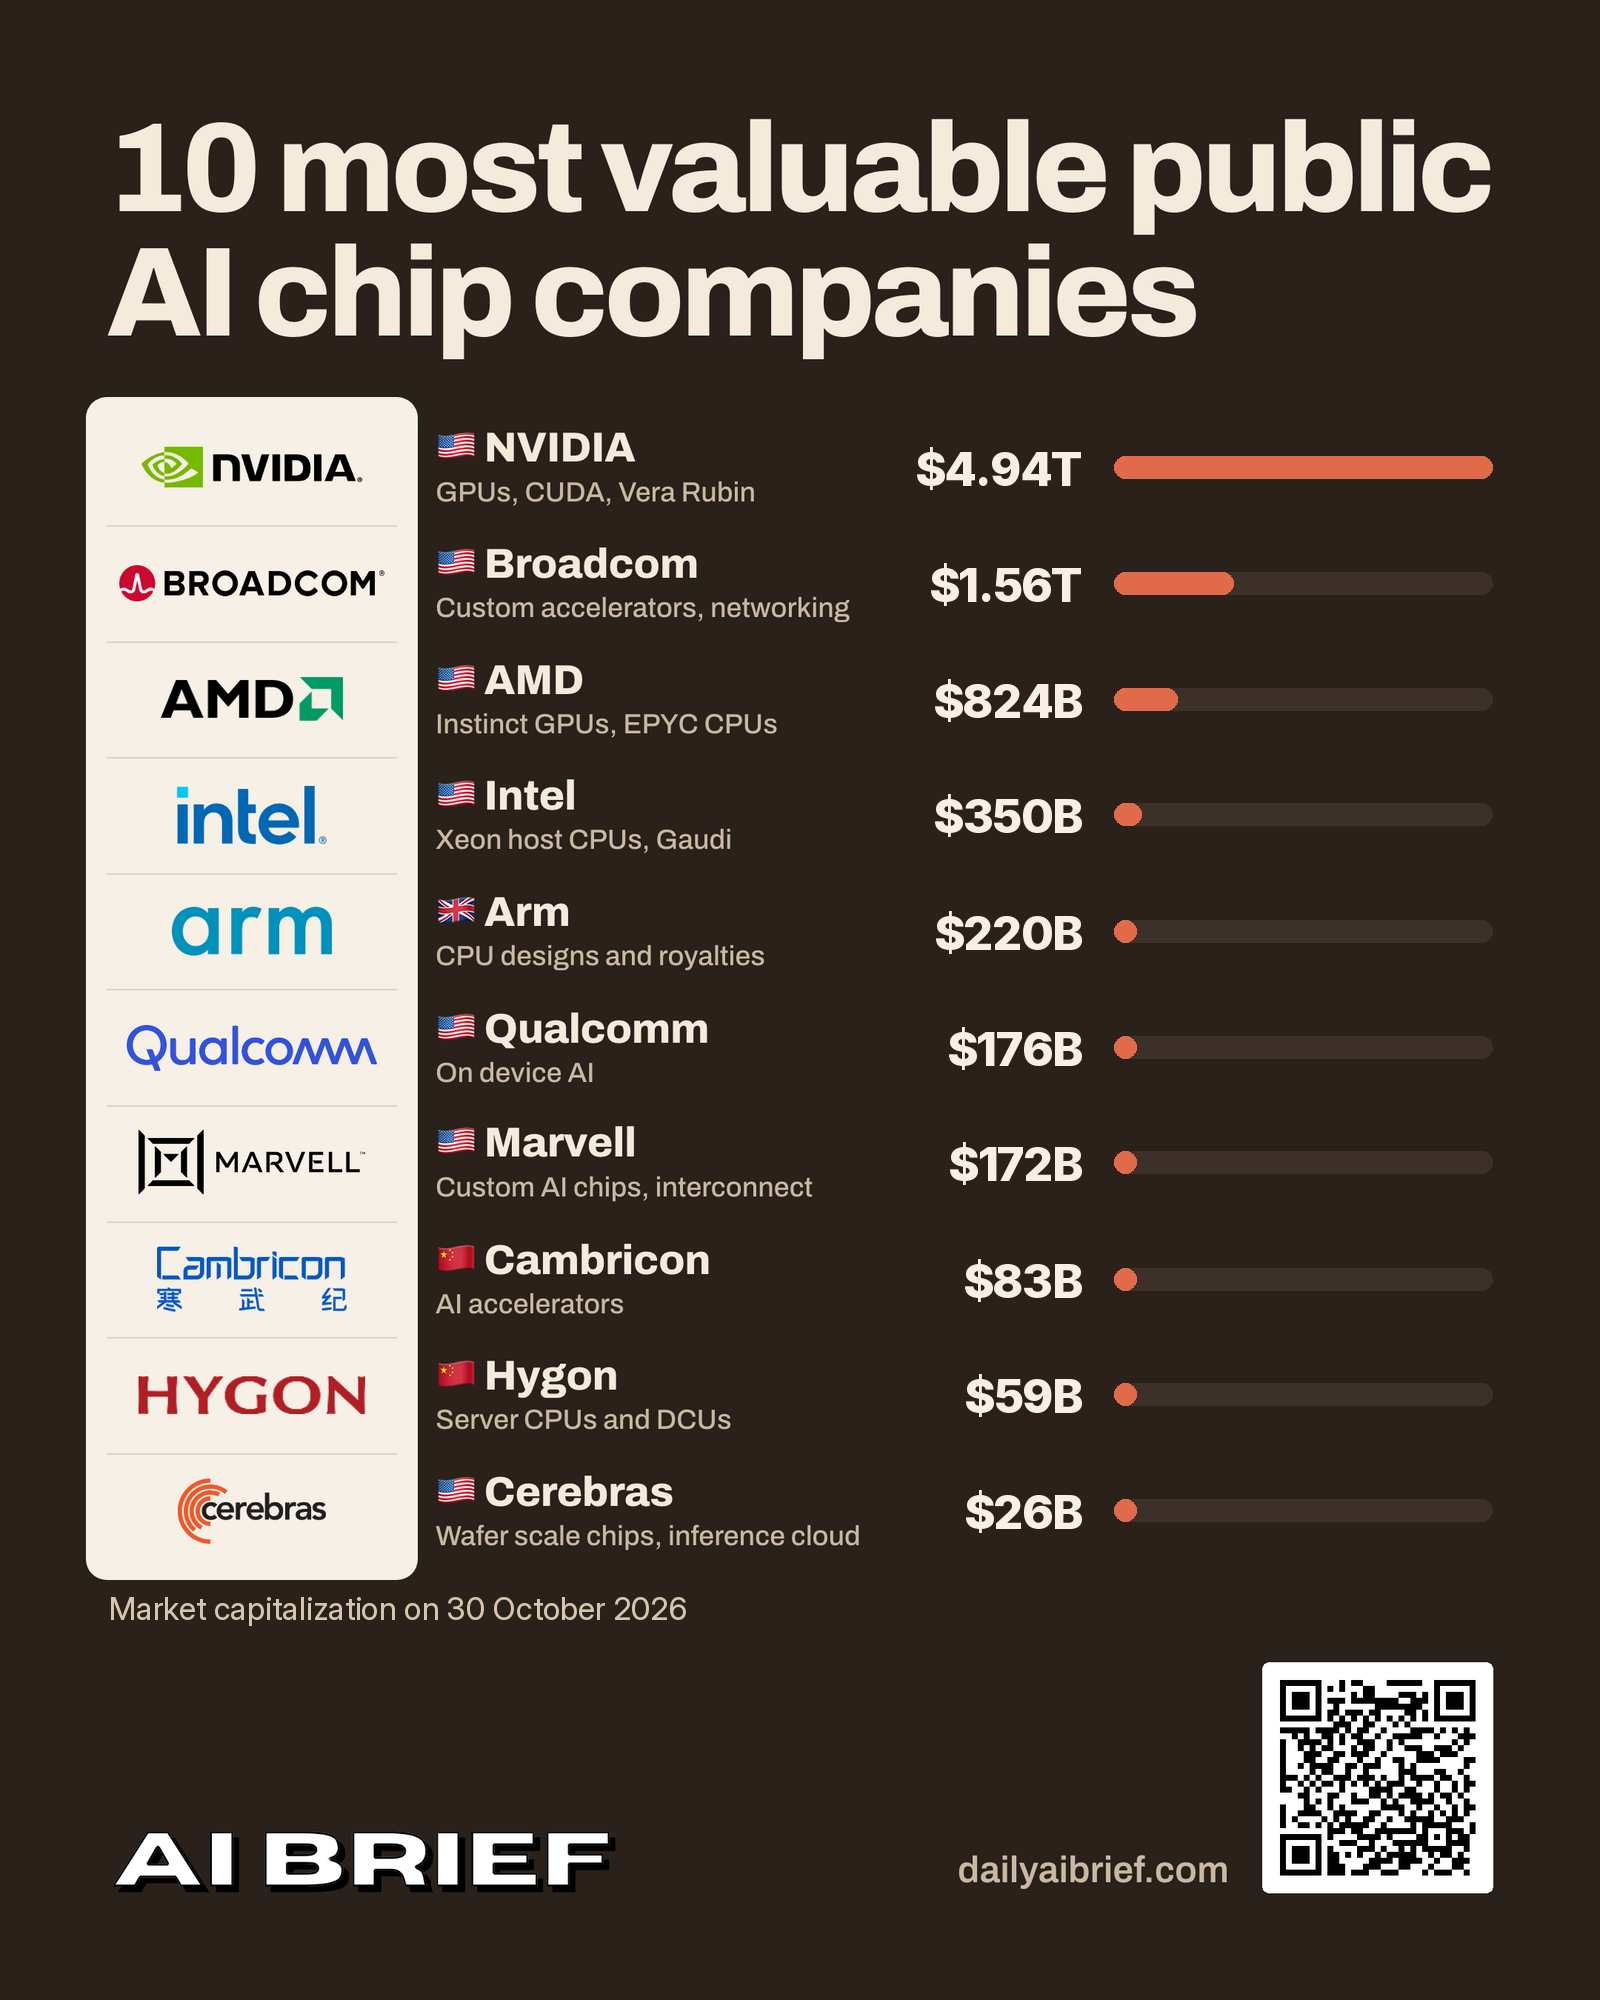
Cerebras inference is coming to Oracle Cloud in 2027
Oct 27, 2026
Chips
Amazon Web Services and Cerebras Systems announced a partnership to provide what they describe as the fastest AI inference available in the cloud, according to a press release. The collaboration will deploy Cerebras CS-3 systems in AWS data centers and make them accessible through Amazon Bedrock in the coming months.
The joint solution combines AWS Trainium processors, optimized for prefill computation, with Cerebras CS-3 hardware, optimized for decode operations. These components are connected through Amazon’s Elastic Fabric Adapter networking, enabling a disaggregated inference architecture that separates the two stages of AI inference—prefill and decode—for greater efficiency and speed.
As detailed by Cerebras, this configuration allows Trainium to handle compute-intensive prefill tasks while the CS-3 focuses on generating output tokens. The companies claim this setup will deliver up to five times more high-speed token capacity within the same hardware footprint compared to traditional GPU-based systems.
The service, available via Amazon Bedrock, will support leading open-source large language models as well as Amazon’s own Nova models. AWS plans to roll out the integrated Trainium and CS-3 inference capability globally later this year.
Consider subscribing to one of our newsletters like Silicon Brief or Daily AI Brief.
Also, consider following us on social media:
Weekly coverage of AI hardware developments including chips, GPUs, cloud platforms, and data center technology.
 Tensordyne
This Tensordyne whitepaper presents Napier, an inference-focused AI processor and rack-scale system based on the company’s TDN Math logarithmic number system. It examines infrastructure requirements for large mixture-of-experts and agentic models, compares major inference architecture approaches, and details the TDN AIP processor, TDN72 pod, TDN Link fabric, and Napier Ultra configuration. The paper reports simulation-based performance, cost, and accuracy-validation results, including Tensordyne’s projected comparison of one Napier rack with a nine-rack Nvidia Rubin plus Groq deployment; the chip is reported as taped out and in fabrication.
Read moreDaily AI Brief: the AI news that matters, in your inbox.