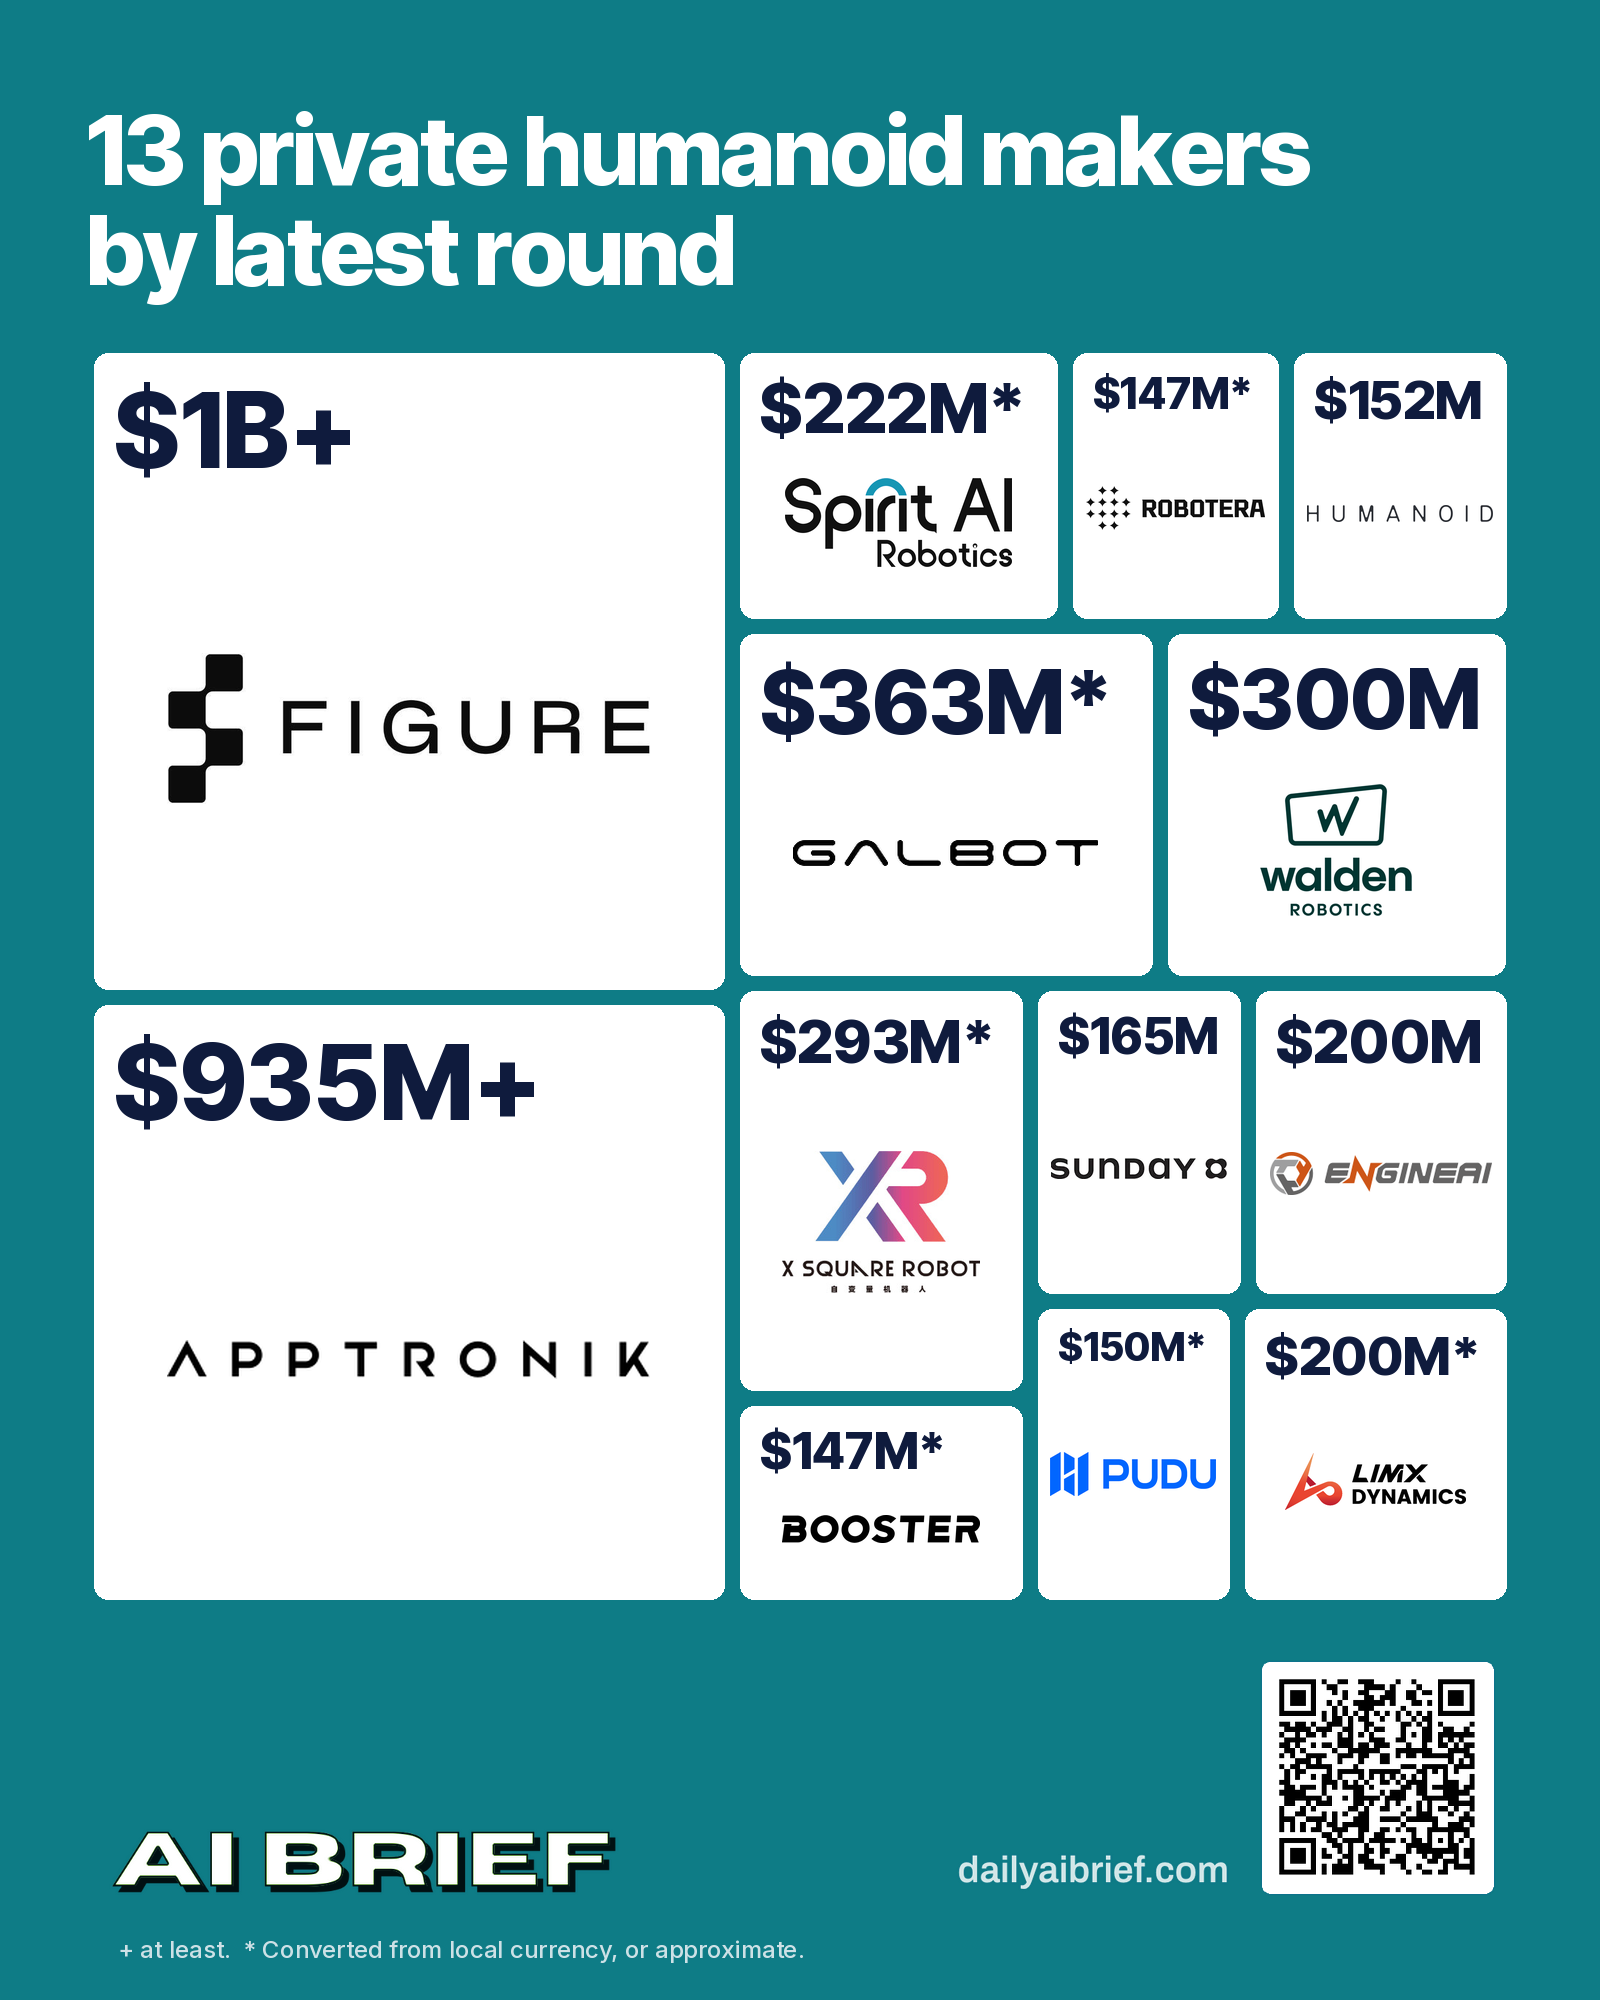
OpenAI Reports Major GPT-6 Coding Gains in COBOL and Fortran
Oct 20, 2026
AI for Software Engineering
Allen Institute for AI (Ai2) introduced StateBench in a blog post, a benchmark that tests how language models track changing information across long documents. It covers four levels of difficulty, from retrieving fixed values to following updates and dependencies between multiple variables.
Ai2 tested open pretrained models and four frontier models. Gemini 3.8 Flash, Claude Opus 5.5, GPT 6 Sol, and GPT 6 Luna performed well on the two easier levels, but accuracy dropped sharply on longer soluble and general finite tasks. Scores reached 13% or less on the longest general finite problems.
Researchers also trained transformer, hybrid, and Gated DeltaNet models with 275 million parameters directly on StateBench. Hybrid and Gated DeltaNet models maintained near perfect results across long sequences on the first three levels, while transformers declined as sequences grew and did not learn the hardest level. A Gated DeltaNet variant remained near perfect on the hardest tasks at about 10 times its maximum training length.
Consider subscribing to one of our newsletters like Daily AI Brief.
Also, consider following us on social media:
Daily report covering major AI developments and industry news, with both top stories and complete market updates
 Tensordyne
This Tensordyne whitepaper presents Napier, an inference-focused AI processor and rack-scale system based on the company’s TDN Math logarithmic number system. It examines infrastructure requirements for large mixture-of-experts and agentic models, compares major inference architecture approaches, and details the TDN AIP processor, TDN72 pod, TDN Link fabric, and Napier Ultra configuration. The paper reports simulation-based performance, cost, and accuracy-validation results, including Tensordyne’s projected comparison of one Napier rack with a nine-rack Nvidia Rubin plus Groq deployment; the chip is reported as taped out and in fabrication.
Read moreDaily AI Brief: the AI news that matters, in your inbox.