LeadDesk Builds Nordic Language Models on AMD Hardware
Oct 23, 2026
Language Models
AMD has announced its first vision language model, Instella-VL-1B, which is trained on AMD's Instinct MI300X GPUs. This model is part of the Instella family of language models introduced by AMD in March 2025. Instella-VL-1B is a multi-modal model featuring 1.5 billion parameters, combining a vision encoder with 300 million parameters and a language model with 1.2 billion parameters.
The model was developed using datasets such as LLaVA, Cambrian, and Pixmo, and was further enhanced with document-related datasets like M-Paper and DocStruct4M. With a new pre-training dataset of 7 million examples and a supervised fine-tuning dataset of 6 million examples, Instella-VL-1B outperforms similarly sized open-source models on general visual language tasks and OCR-related benchmarks.
AMD has made Instella-VL-1B fully open-source, sharing not only the model weights but also detailed training configurations, datasets, and code. This initiative underscores AMD's commitment to advancing open-source AI technology in the field of multimodal AI.
Consider subscribing to one of our newsletters like Silicon Brief or Daily AI Brief.
Also, consider following us on social media:
Weekly coverage of AI hardware developments including chips, GPUs, cloud platforms, and data center technology.
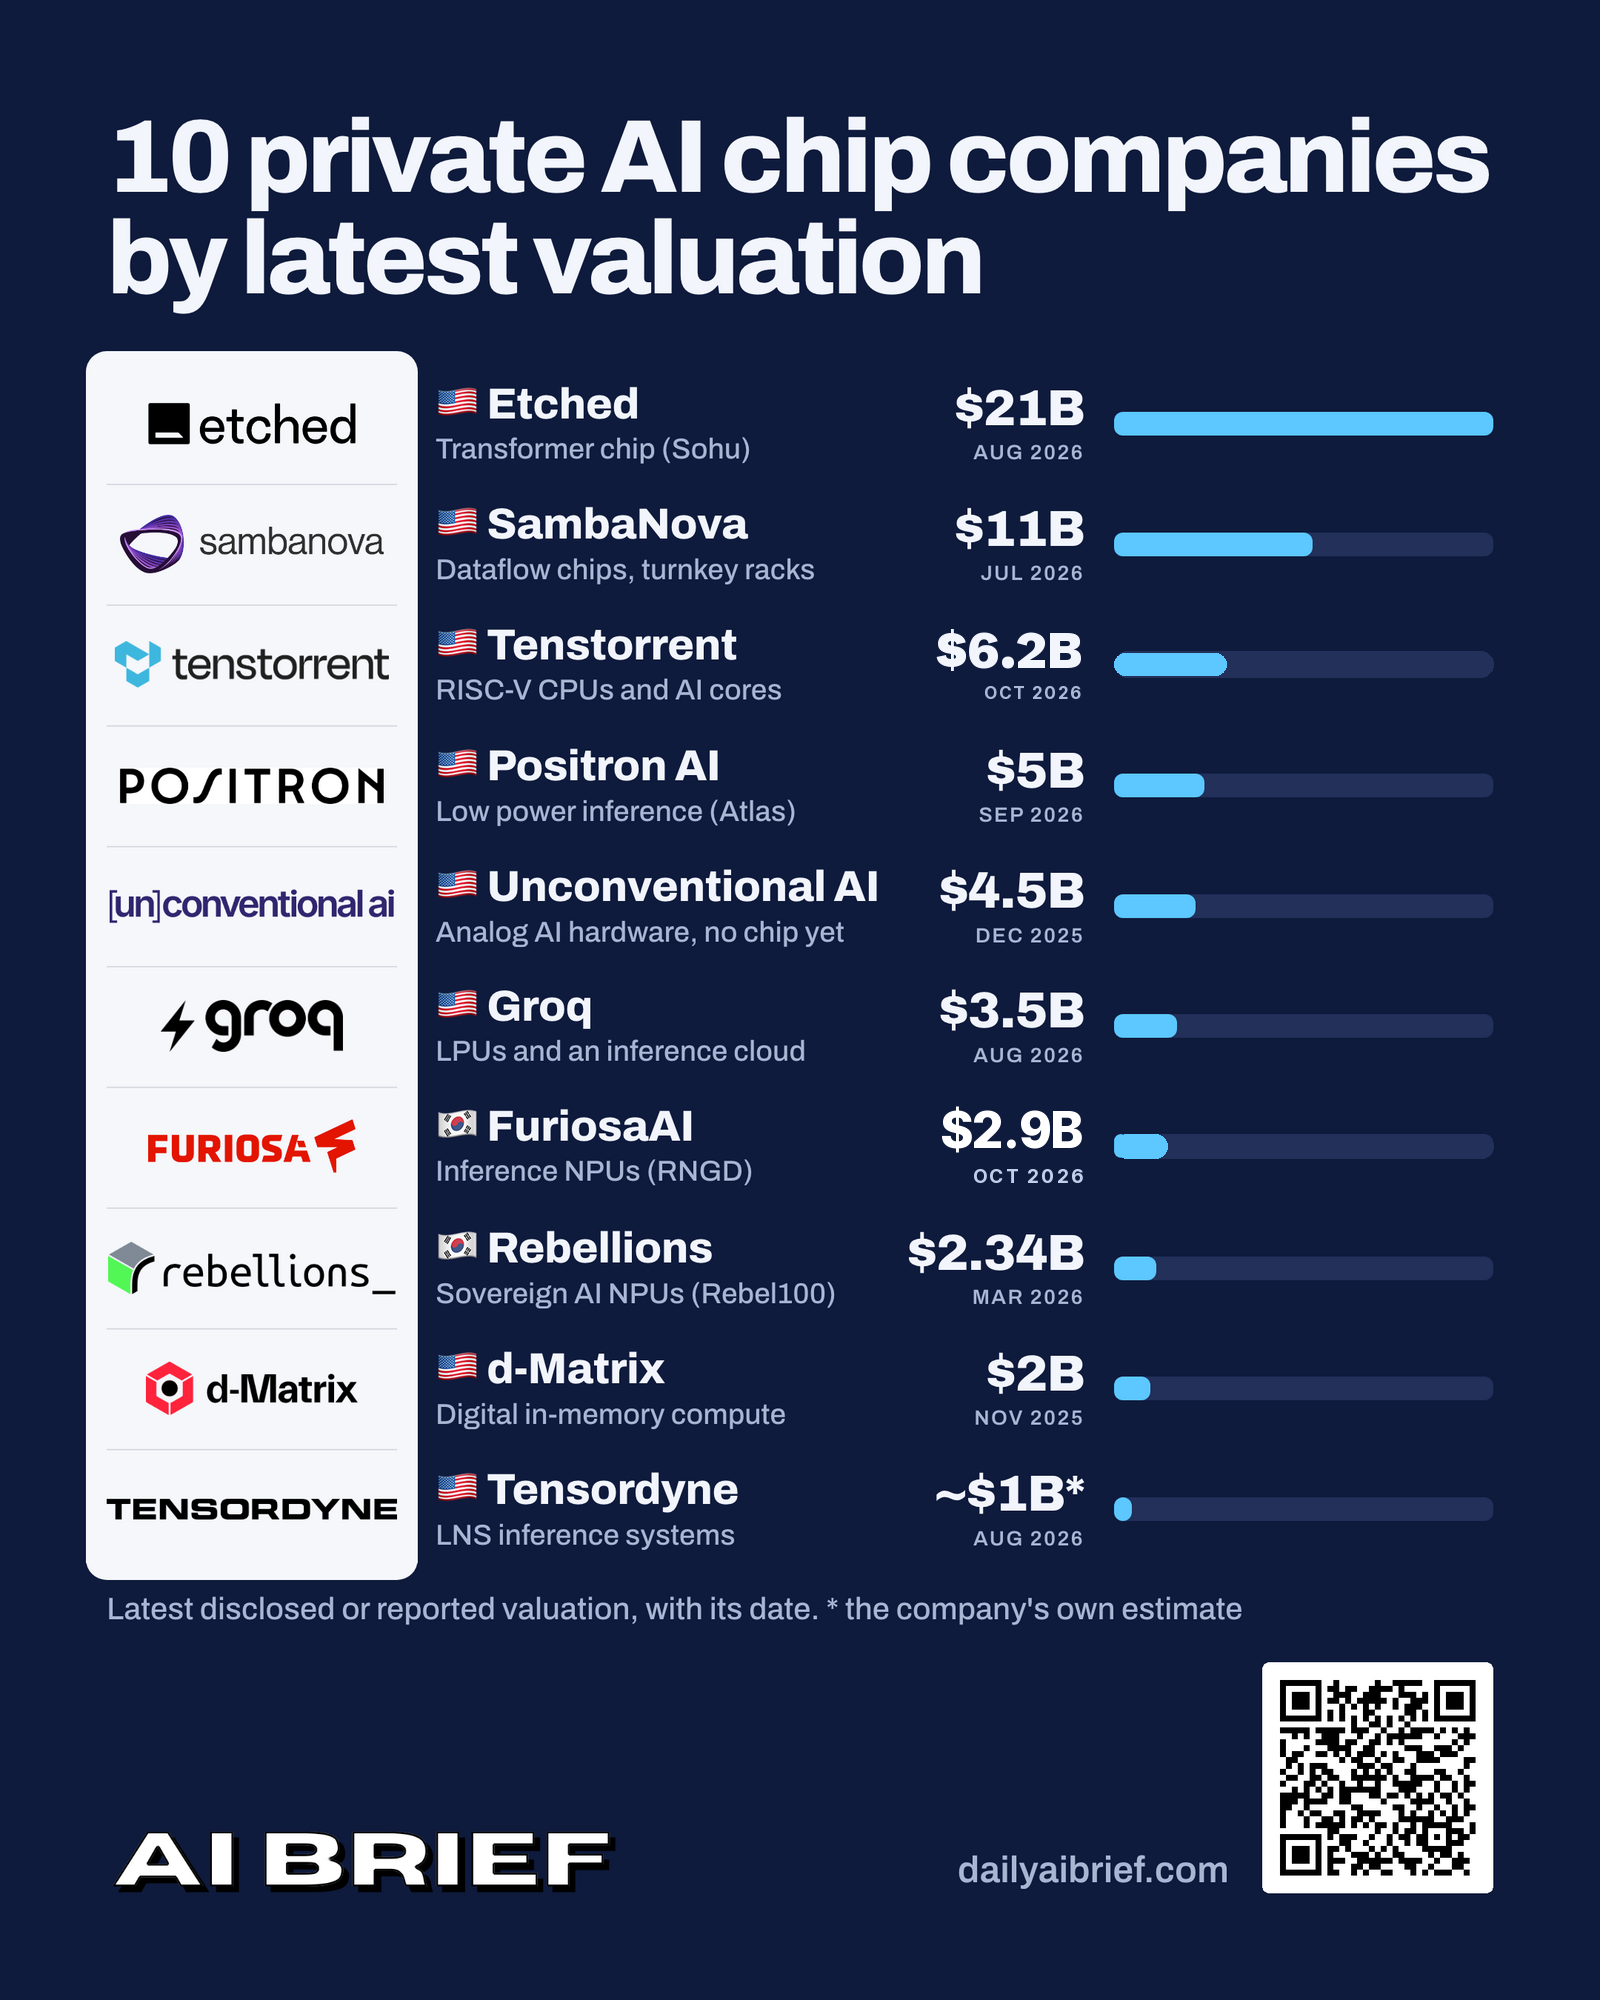
 Tensordyne
This Tensordyne whitepaper presents Napier, an inference-focused AI processor and rack-scale system based on the company’s TDN Math logarithmic number system. It examines infrastructure requirements for large mixture-of-experts and agentic models, compares major inference architecture approaches, and details the TDN AIP processor, TDN72 pod, TDN Link fabric, and Napier Ultra configuration. The paper reports simulation-based performance, cost, and accuracy-validation results, including Tensordyne’s projected comparison of one Napier rack with a nine-rack Nvidia Rubin plus Groq deployment; the chip is reported as taped out and in fabrication.
Read moreDaily AI Brief: the AI news that matters, in your inbox.