Mistral AI Launches Voxtral 3 Voice Models and Agent SDK
Oct 20, 2026
Voice & Audio AI
Zyphra released ZONOS3-Mini, a compact text to speech model for zero shot voice cloning, as detailed in a company post. The model is available under the Apache 2.0 license and can run locally in browsers, on phones, on computers and on servers.
ZONOS3-Mini is a sparse mixture of experts model with 100 million active parameters and 800 million total parameters. Zyphra trained it on 112 Nvidia H100 GPUs over 2.5 days. The company measured time to first audio below 570 milliseconds in a browser on a Pixel 9 and below 150 milliseconds on an M3 MacBook Air.
The model supports controls for speaker identity, accent, age, gender, pace, emotion, projection and liveliness. Its runtimes include WebGPU for browsers, SGLang and vLLM for servers, and GGML for other devices. The model weights are available on Hugging Face, while the runtimes are available on GitHub.
Consider subscribing to one of our newsletters like Daily AI Brief.
Also, consider following us on social media:
Daily report covering major AI developments and industry news, with both top stories and complete market updates
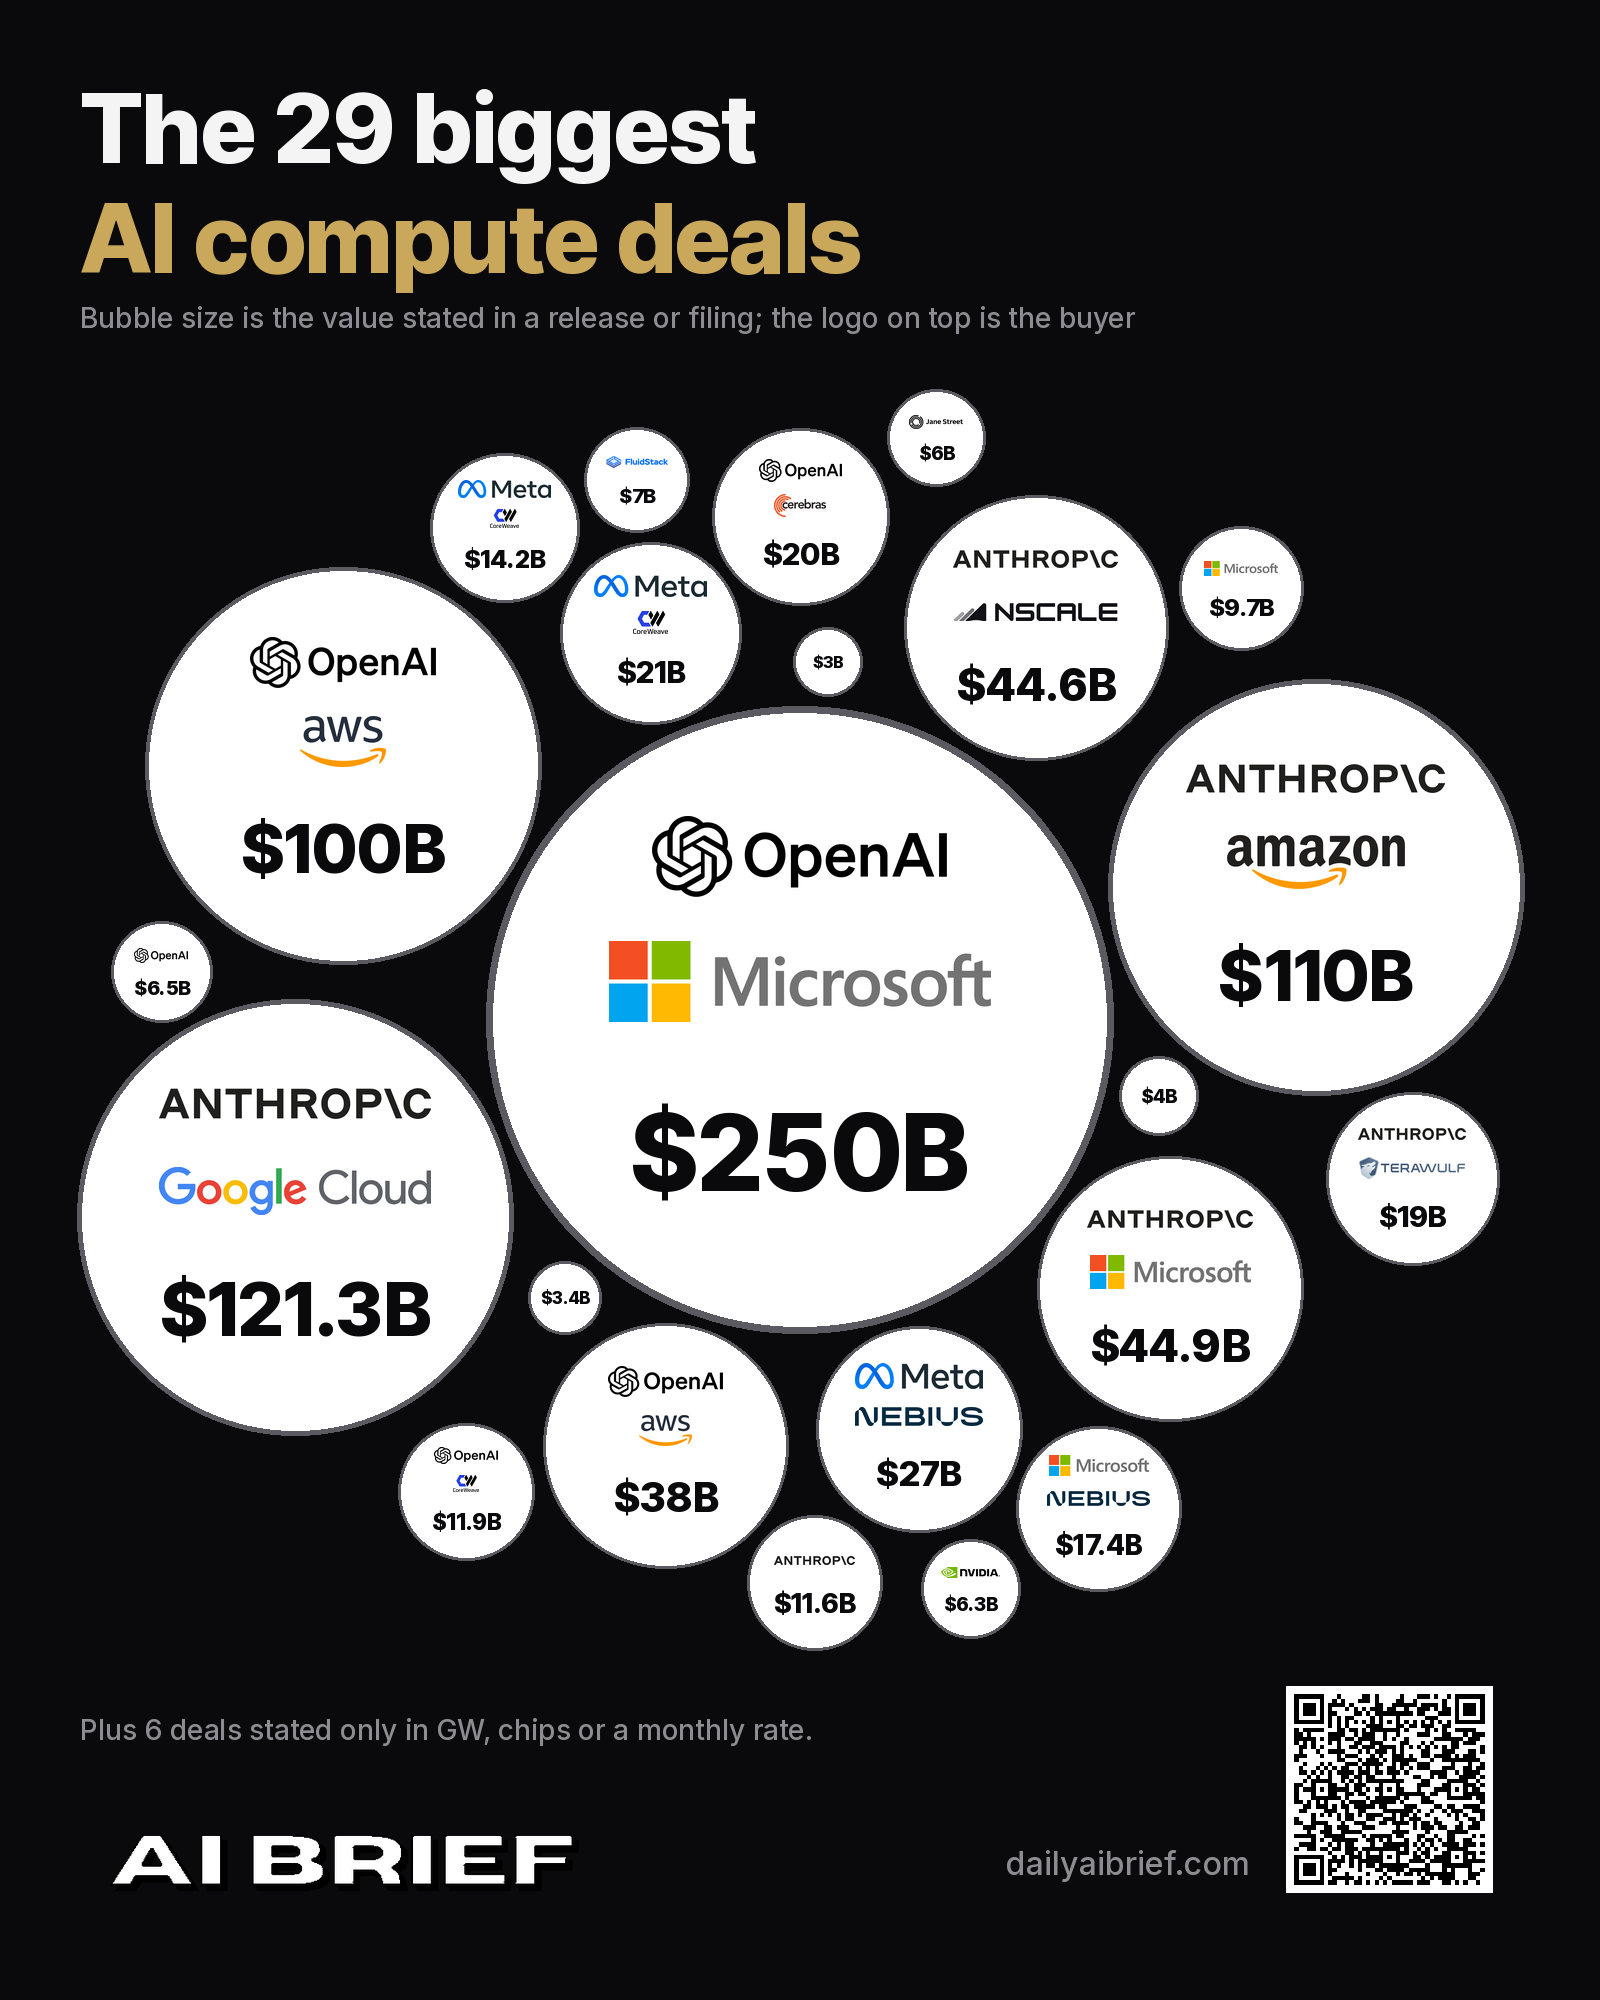
The largest announced contracts to buy chips or cloud capacity for AI
 Tensordyne
This Tensordyne whitepaper presents Napier, an inference-focused AI processor and rack-scale system based on the company’s TDN Math logarithmic number system. It examines infrastructure requirements for large mixture-of-experts and agentic models, compares major inference architecture approaches, and details the TDN AIP processor, TDN72 pod, TDN Link fabric, and Napier Ultra configuration. The paper reports simulation-based performance, cost, and accuracy-validation results, including Tensordyne’s projected comparison of one Napier rack with a nine-rack Nvidia Rubin plus Groq deployment; the chip is reported as taped out and in fabrication.
Read moreDaily AI Brief: the AI news that matters, in your inbox.