NVIDIA Brings DSX Power and Cooling Controls to European AI Factories
Oct 21, 2026
Data Centers
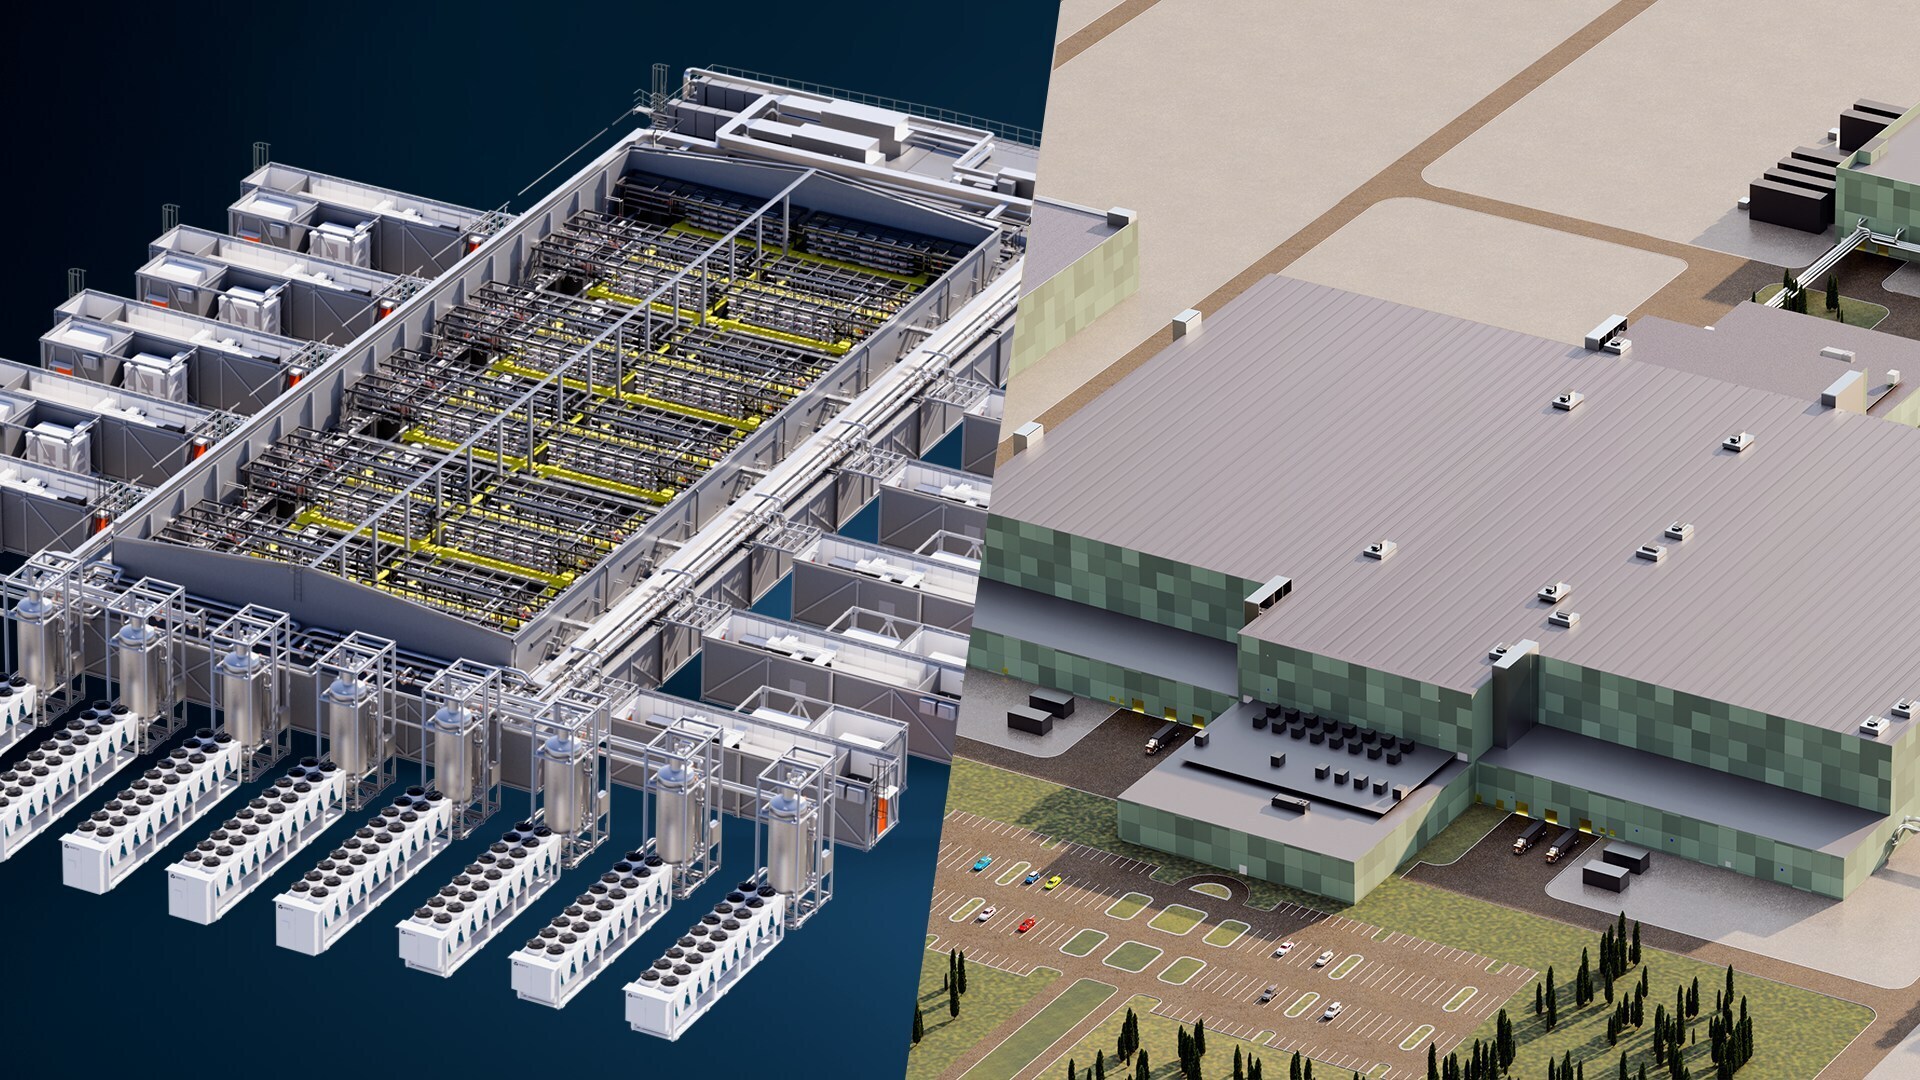
Vertiv announced in a press release the launch of its gigawatt-scale reference architectures for the NVIDIA Omniverse DSX Blueprint. The designs aim to reduce Time to First Token by up to 50% for large-scale generative AI systems and support deployment on platforms such as NVIDIA Vera Rubin.
The new architectures use the Vertiv OneCore platform, which integrates compute, power, cooling, and services into a unified system. This prefabricated approach allows deployment flexibility across stick-built, hybrid, and fully prefabricated models, enabling faster implementation of AI factory infrastructure.
Vertiv’s reference designs feature optimized power topologies and advanced liquid cooling systems to manage high thermal loads from accelerated computing. The integration of digital twin simulations through SimReady 3D assets allows customers to model and validate AI factory designs before construction.
According to Vertiv, these architectures are already being applied in the design of several large-scale AI factory projects, providing scalable, energy-efficient infrastructure for multi-generational AI platforms.
Consider subscribing to one of our newsletters like Silicon Brief or Daily AI Brief.
Also, consider following us on social media:
Weekly coverage of AI hardware developments including chips, GPUs, cloud platforms, and data center technology.
 Tensordyne
This Tensordyne whitepaper presents Napier, an inference-focused AI processor and rack-scale system based on the company’s TDN Math logarithmic number system. It examines infrastructure requirements for large mixture-of-experts and agentic models, compares major inference architecture approaches, and details the TDN AIP processor, TDN72 pod, TDN Link fabric, and Napier Ultra configuration. The paper reports simulation-based performance, cost, and accuracy-validation results, including Tensordyne’s projected comparison of one Napier rack with a nine-rack Nvidia Rubin plus Groq deployment; the chip is reported as taped out and in fabrication.
Read moreDaily AI Brief: the AI news that matters, in your inbox.