Baidu releases ERNIE 5.5 Flash Preview with open weights due by 25 November
Nov 12, 2026
Chips
Edge0 has released Edge0-145B and Edge0-120B, open-weight sparse mixture-of-experts models built to run on a single consumer NVIDIA GPU, according to the model card on Hugging Face. The models are derived from Qwen3.8-Flash-Next and use 512 experts with 10 active per token, a 256,000-token context and native 4-bit training.
Edge0 reports 121.2 tokens per second for agent decoding and a score of 86.5 on Terminal-Bench 2.1 for the 145B model in its Q3_K format on an RTX 5090 D with 24 GB of memory. The figures are Edge0's own measurements. The models use Edge0's own community licence on top of Qwen's licence, which allows research, internal use and commercial use of outputs but not selling the model or running it as a commercial service without separate permission.
Consider subscribing to one of our newsletters like Daily AI Brief.
Also, consider following us on social media:
Daily report covering major AI developments and industry news, with both top stories and complete market updates
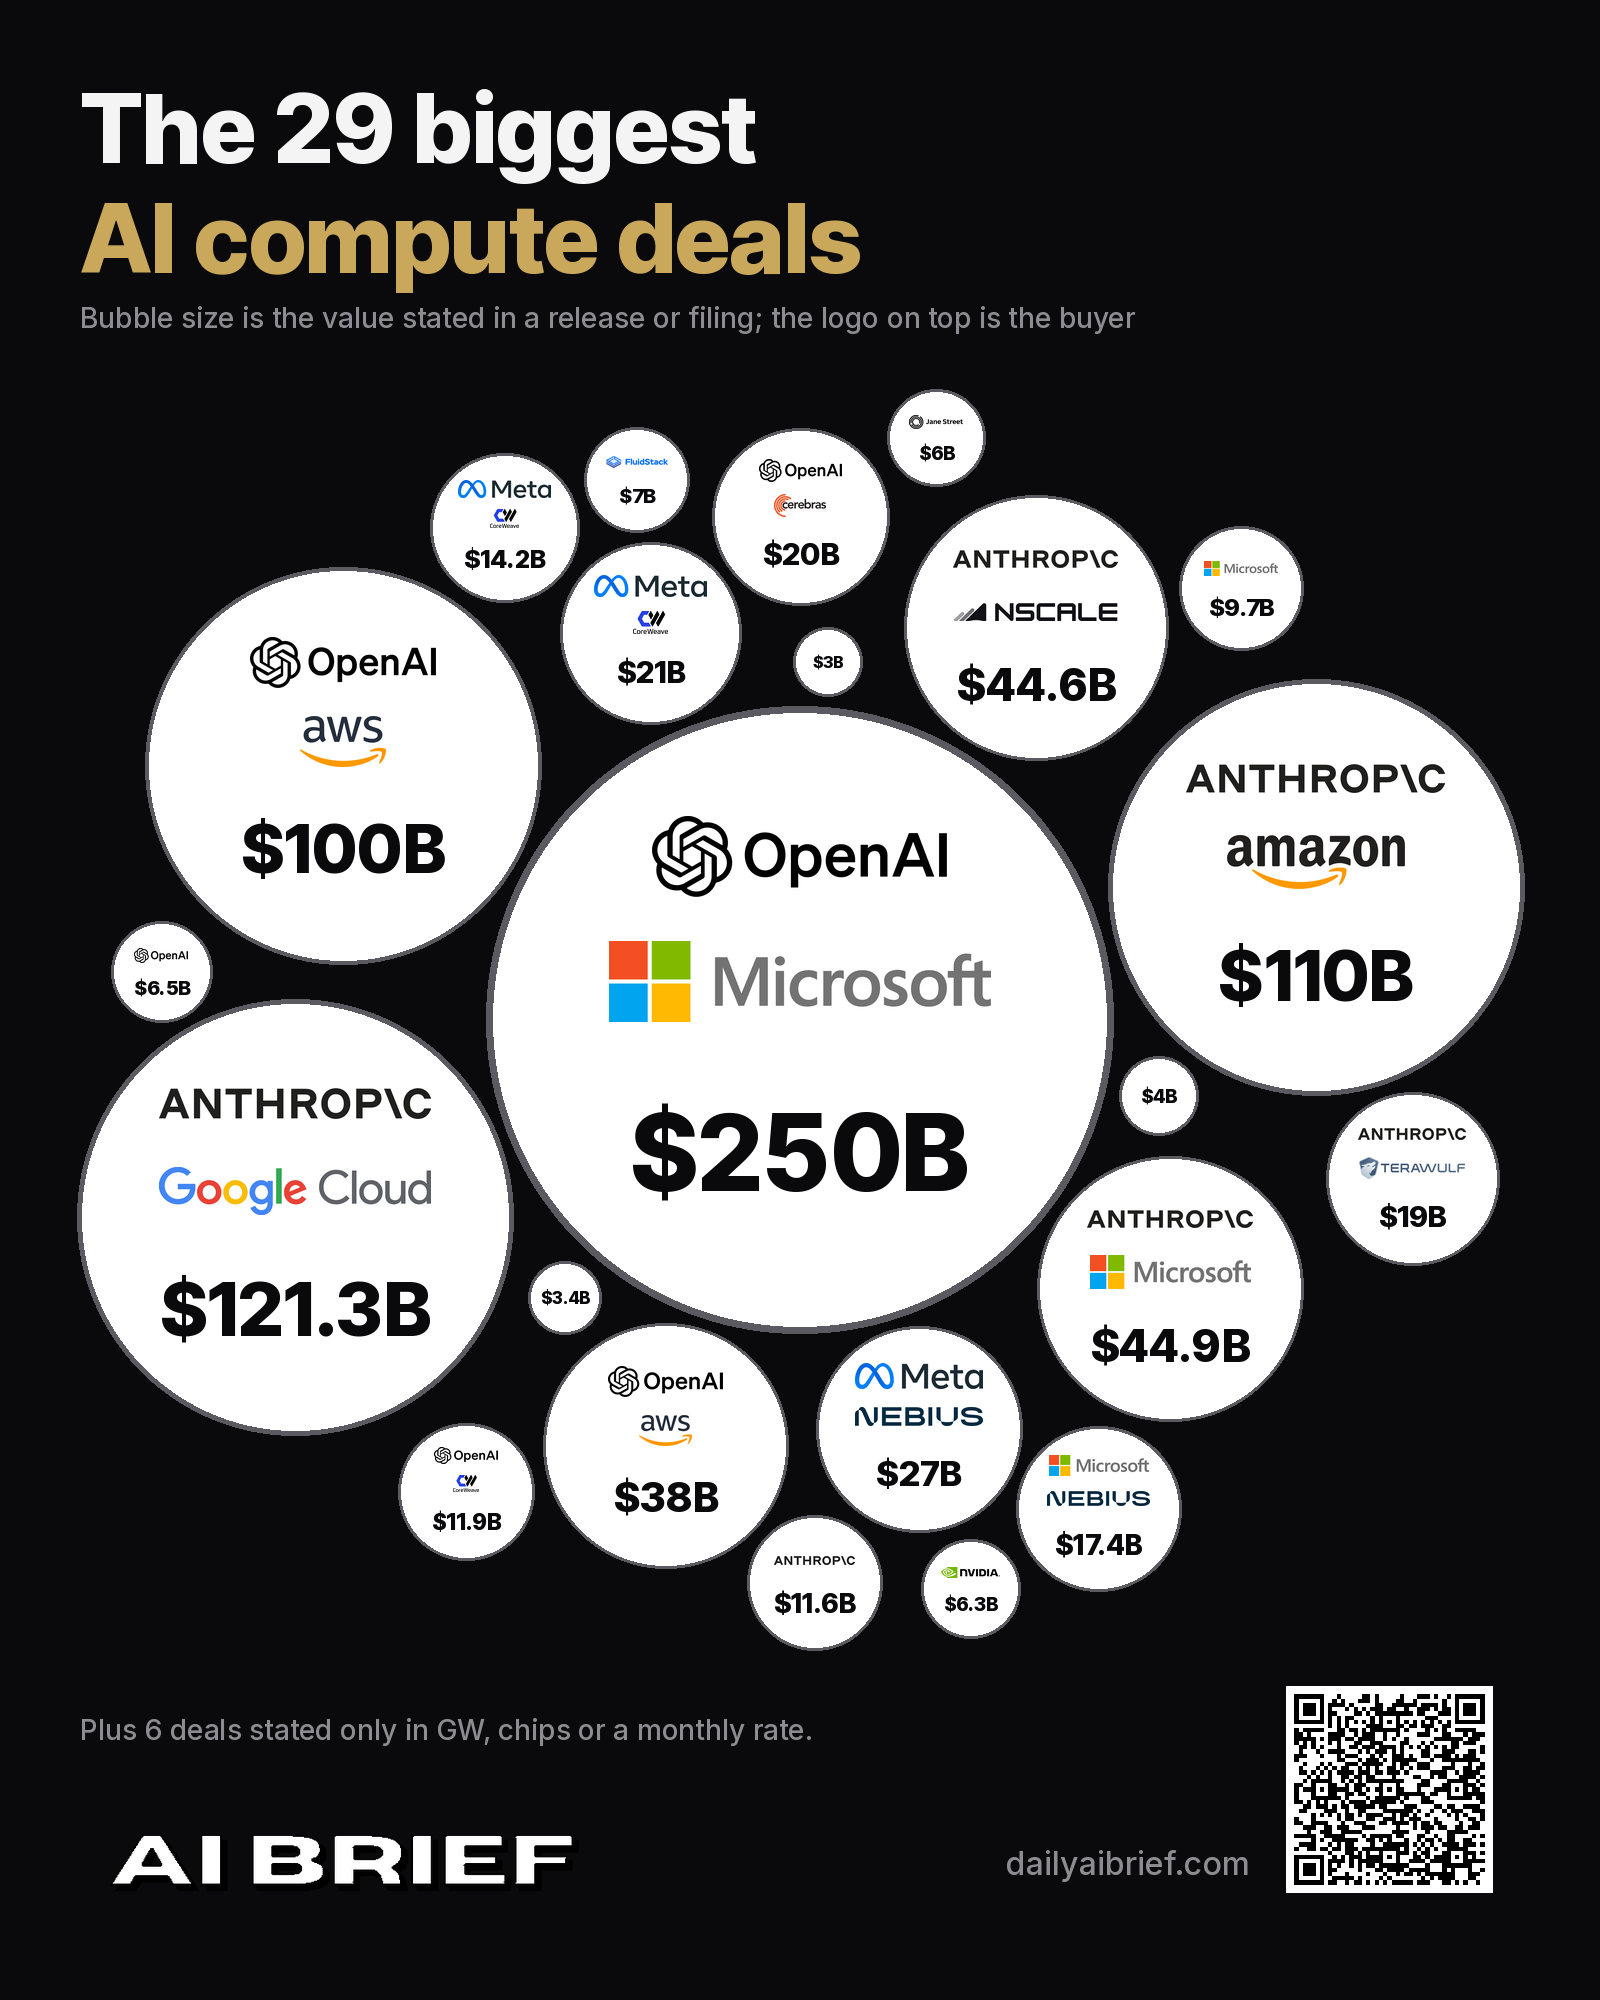
The largest announced contracts to buy chips or cloud capacity for AI
 Tensordyne
This Tensordyne whitepaper presents Napier, an inference-focused AI processor and rack-scale system based on the company’s TDN Math logarithmic number system. It examines infrastructure requirements for large mixture-of-experts and agentic models, compares major inference architecture approaches, and details the TDN AIP processor, TDN72 pod, TDN Link fabric, and Napier Ultra configuration. The paper reports simulation-based performance, cost, and accuracy-validation results, including Tensordyne’s projected comparison of one Napier rack with a nine-rack Nvidia Rubin plus Groq deployment; the chip is reported as taped out and in fabrication.
Read moreDaily AI Brief: the AI news that matters, in your inbox.